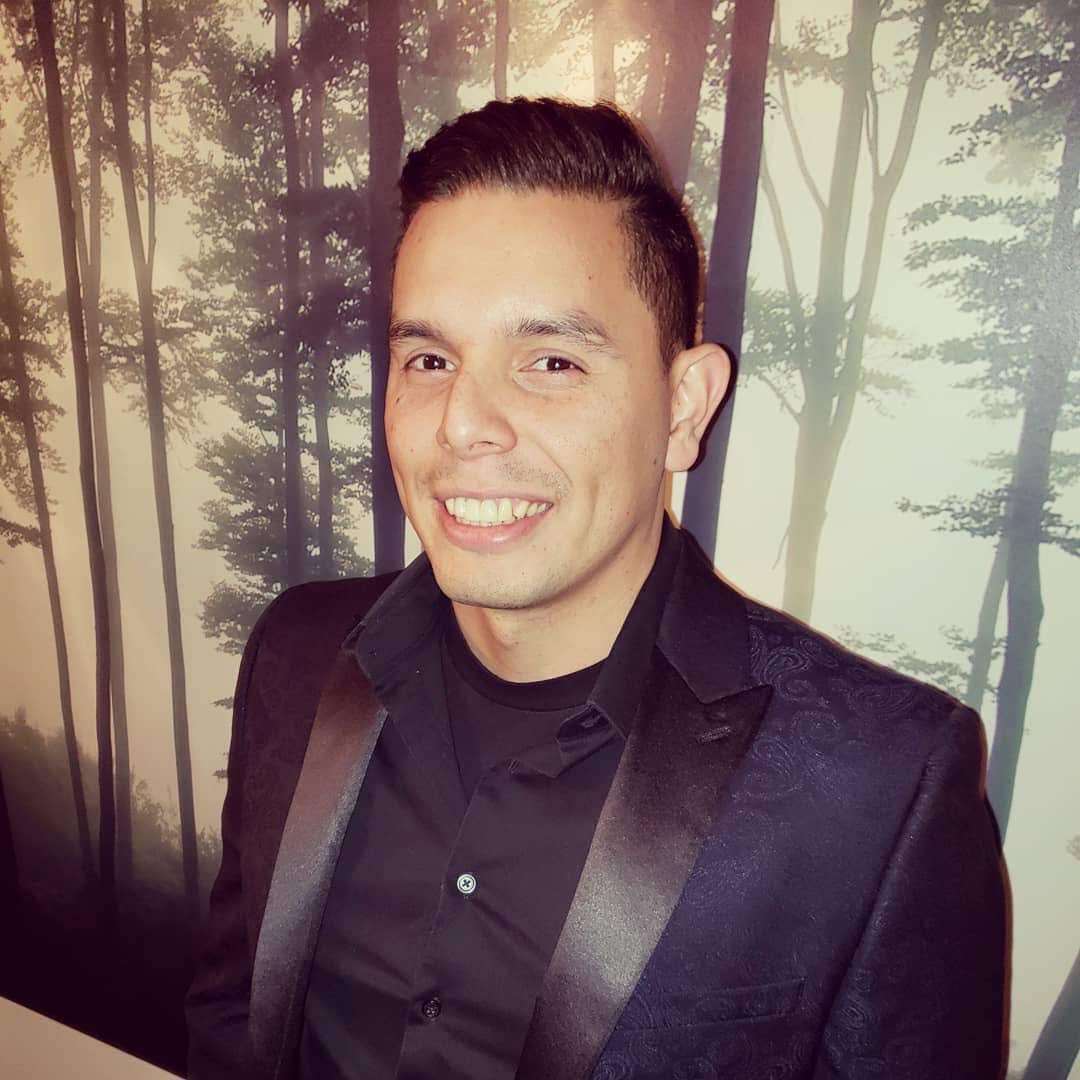
Ruben Villegas
I am a Senior Staff Research Scientist at Google DeepMind where I work on multi-modal generative models and world models.
I received my PhD from the Computer Science & Engineering Department at the University of Michigan, Ann Arbor under the supervision of Professor Honglak Lee. During my PhD, I mainly focused on building conditional video generation models and contributed to one of the first world models from pixels successfully used to improve sample-efficiency in model-based reinforcement learning.
Fun Facts: I played for my national basketball team (I am originally from Ecuador). I was also second best scorer in the nation in a national championship I played back in the day. I was part of a team that beat the media's projected champion during a championship in Quito (the guy that was best scorer in the national championship played for the other team :P). Let's have a Curry-range 3-point shootout. Ok, I'll stop now ...


